In-software Pandas/PySpark switching
Problem
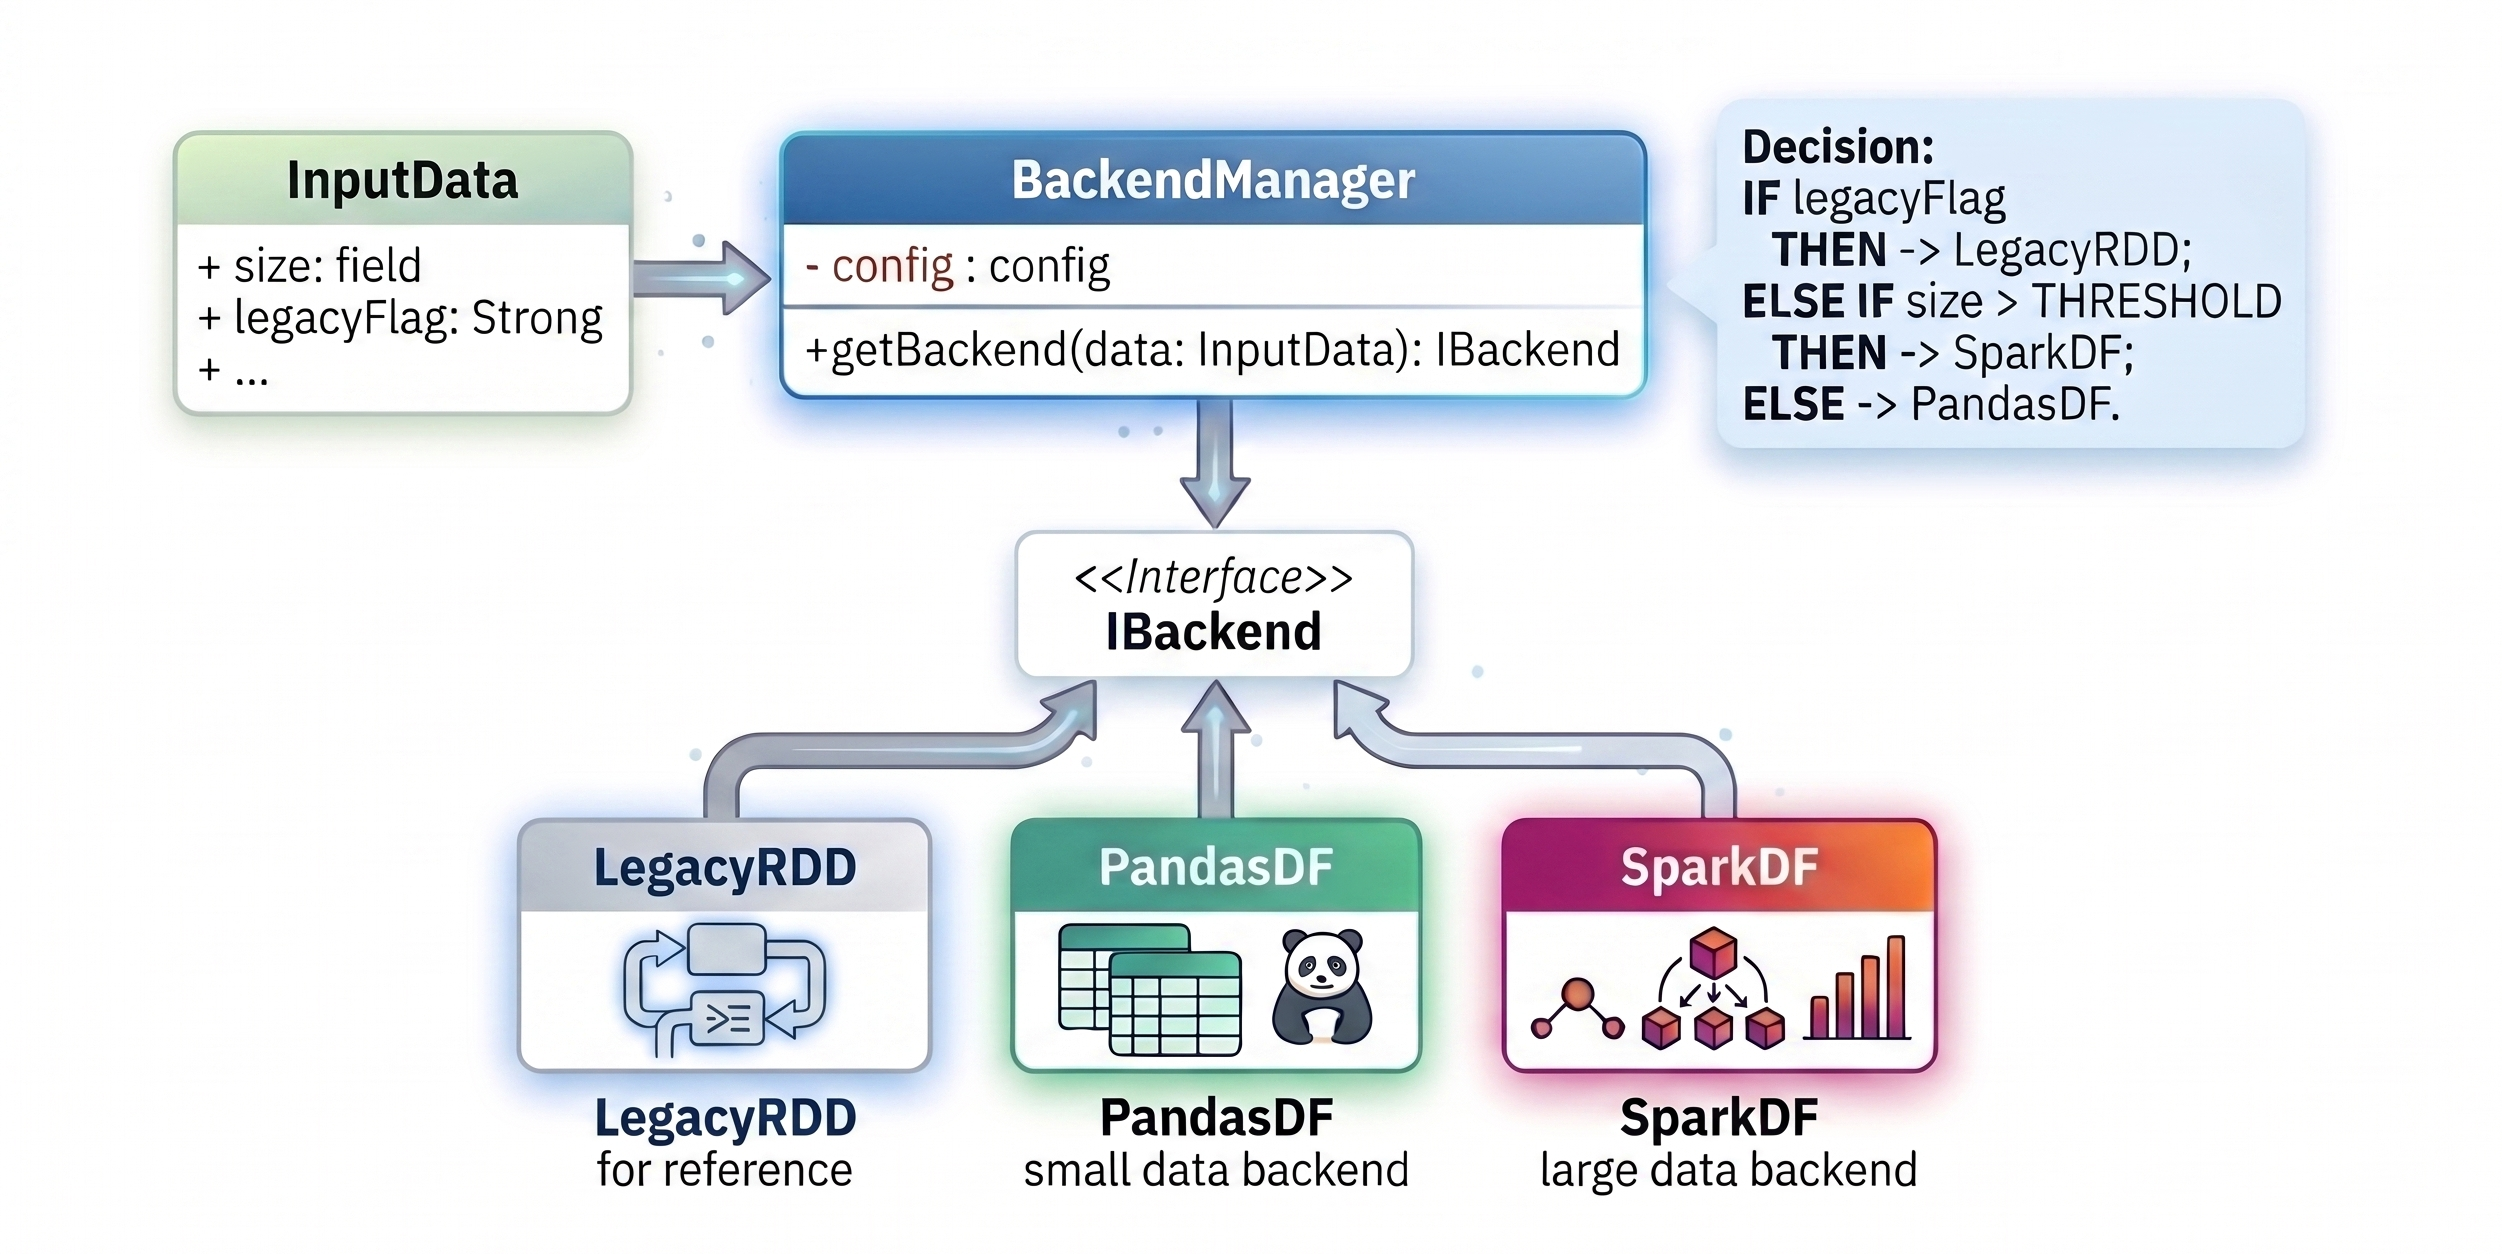
A legacy product for multiple regression had been implemented using Spark RDDs. The person who wrote the code had left. The code was becoming difficult to maintain or extend and wasteful for small datasets.
Contribution
- refactored the code, allowing for a change of computational backends
- added two more computational backends, one with PySpark and one with Pandas
- in-software switching among all three backends
- introduced tests and best software engineering practices
Outcomes
- 20x speed-up for small datasets, when the data small enough for Pandas
- 1-5x speed-up for larger datasets
- flexible and future-proof code.